Long PDFs rarely contain just one kind of information. A research report may explain its findings in dozens of pages while presenting the evidence in dense tables, charts, appendices, and footnotes. A financial report can tell one story in its narrative sections while the numbers in its tables provide the evidence behind that story.
That makes PDF review a two-part task: understand what the document says, then verify whether the underlying data supports it.
This is where iBoomto can fit into a practical document-review workflow. Its tools separate quick PDF summarization from structured table extraction, while its Windows AI agent is designed for longer, multi-step document workflows.
Start with the narrative: summarize the PDF
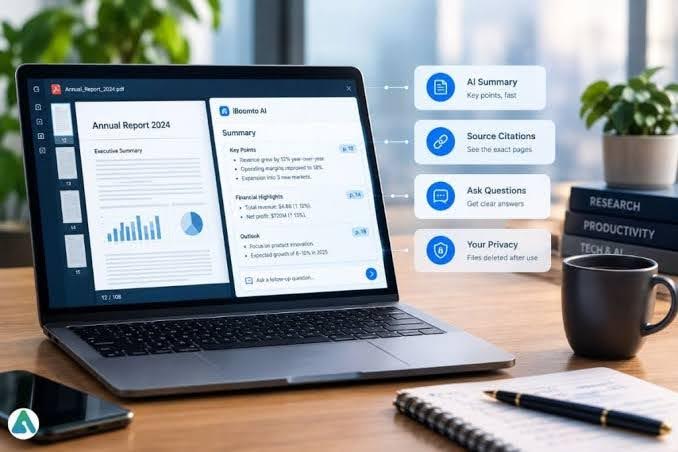
The first step is to establish the document’s overall argument. Instead of manually scanning every page, use the iBoomto AI PDF summarizer to identify the main arguments, findings, data points, and conclusions.
The summarizer produces structured output rather than simply reducing the PDF to a block of text. It can organize key points, provide chapter-level takeaways, and answer follow-up questions in natural language. More importantly for research and professional work, its summary points can link back to source pages so readers can check the original context.
For example, after uploading a 100-page industry report, you might first ask:
- What is the report’s central conclusion?
- What changed compared with the previous period?
- Which findings does the author consider most important?
- What assumptions or limitations are mentioned?
This gives you the narrative layer of the review.
Then separate the numbers from the prose
A summary can tell you that revenue increased, costs fell, or a study found a significant relationship. But if the conclusion depends on precise figures, you should inspect the tables independently.
The iBoomto PDF Table Extractor is designed to focus specifically on structured table data. It can detect tables in text-based, scanned, and image-based PDFs, and export extracted data to Excel, CSV, or JSON. The tool also aims to preserve structures such as merged cells, multi-level headers, and tables that continue across multiple pages.
Picture suggestion — PDF table extraction
This separation matters because PDF tables can be surprisingly difficult to work with. A visually clear table may not contain an underlying data structure that can simply be copied into a spreadsheet. Scanned documents, borderless tables, merged cells, and multi-level headers can all introduce extraction problems.
With extracted data in Excel or CSV, you can independently calculate totals, growth rates, averages, percentage changes, or other metrics instead of relying solely on an AI-generated interpretation.
Cross-check the conclusion against the figures
The most valuable step is not summarization or extraction alone. It is a comparison.
Suppose a report says that sales increased by 18%. Extract the relevant table and calculate the change yourself. Does the table actually support 18%? Are the comparison periods the same? Is the percentage based on revenue, units, or another metric? Are there footnotes that change how the number should be interpreted?
The same approach works for research papers. If the narrative claims that one group performed better than another, extract the relevant results table and check the reported values. If the report highlights a particular regional trend, compare that claim against the underlying rows and columns.
This creates a simple review chain:
Narrative → Extracted data → Independent check → Verified conclusion
It is a more reliable approach than asking an AI system to summarize everything and accepting the resulting conclusions without inspection.
From one-off tasks to deeper Windows workflows
For an occasional PDF, the online tools can provide a straightforward starting point. iBoomto also positions its Windows AI document agent for more comprehensive workflows involving multiple files and stages.
The Windows software can work with PDFs as well as Word, Excel, PowerPoint, CSV, images, text files, web content, and other formats. Its workflow can combine extraction, analysis, verification, summarization, organization, and document generation rather than treating each task as an isolated conversion. IiBoomto
Privacy is another consideration when documents contain sensitive information. iBoomto says its Windows agent keeps original files on the local device, while some AI-assisted operations may temporarily send the content required to an AI model; that temporary data is purged after processing. The company also describes local processing and security controls for sensitive document workflows.
For users who want to move beyond a single online task, this Windows approach can make sense: start with one PDF, then progress toward batch processing, cross-document comparisons, structured datasets, and report generation.
A practical way to use iBoomto for data-heavy PDFs
The workflow can be simple:
- Summarize the PDF to understand its narrative and major conclusions.
- Locate the supporting tables mentioned in the text.
- Extract those tables into Excel, CSV, or JSON.
- Check the figures independently using calculations or comparisons.
- Return to the source pages whenever a number or conclusion matters.
- Use the Windows AI agent when the review expands across multiple documents or requires several connected steps.
The key idea is not to make AI the final authority. Instead, use it to make the review process faster while keeping the original document and its figures in the verification loop.
Free access, with an important distinction
iBoomto offers free online PDF tools, including its PDF summarizer and table extractor, making them useful for individual document tasks.
For the “no token limit” point, it is worth being precise: iBoomto’s current online tools do have usage/credit limitations in some scenarios, while its paid AI plans also use credits. So the strongest and safest wording is to position local/on-device workflows as avoiding dependence on an online token allowance, rather than claiming that every iBoomto mode has absolutely no token or usage limits.
Ultimately, reviewing a data-heavy PDF is not just about getting a shorter version of the document. It is about connecting the story to the evidence. By separating text summarization from table extraction and then cross-checking the two, iBoomto can help turn a long PDF from something you merely skim into something you can analyze with greater confidence.